

- A sudden jump in duplicate rows due to a faulty join
- A decrease in a data source due to an upstream error
- A system failure caused no new records to be inserted
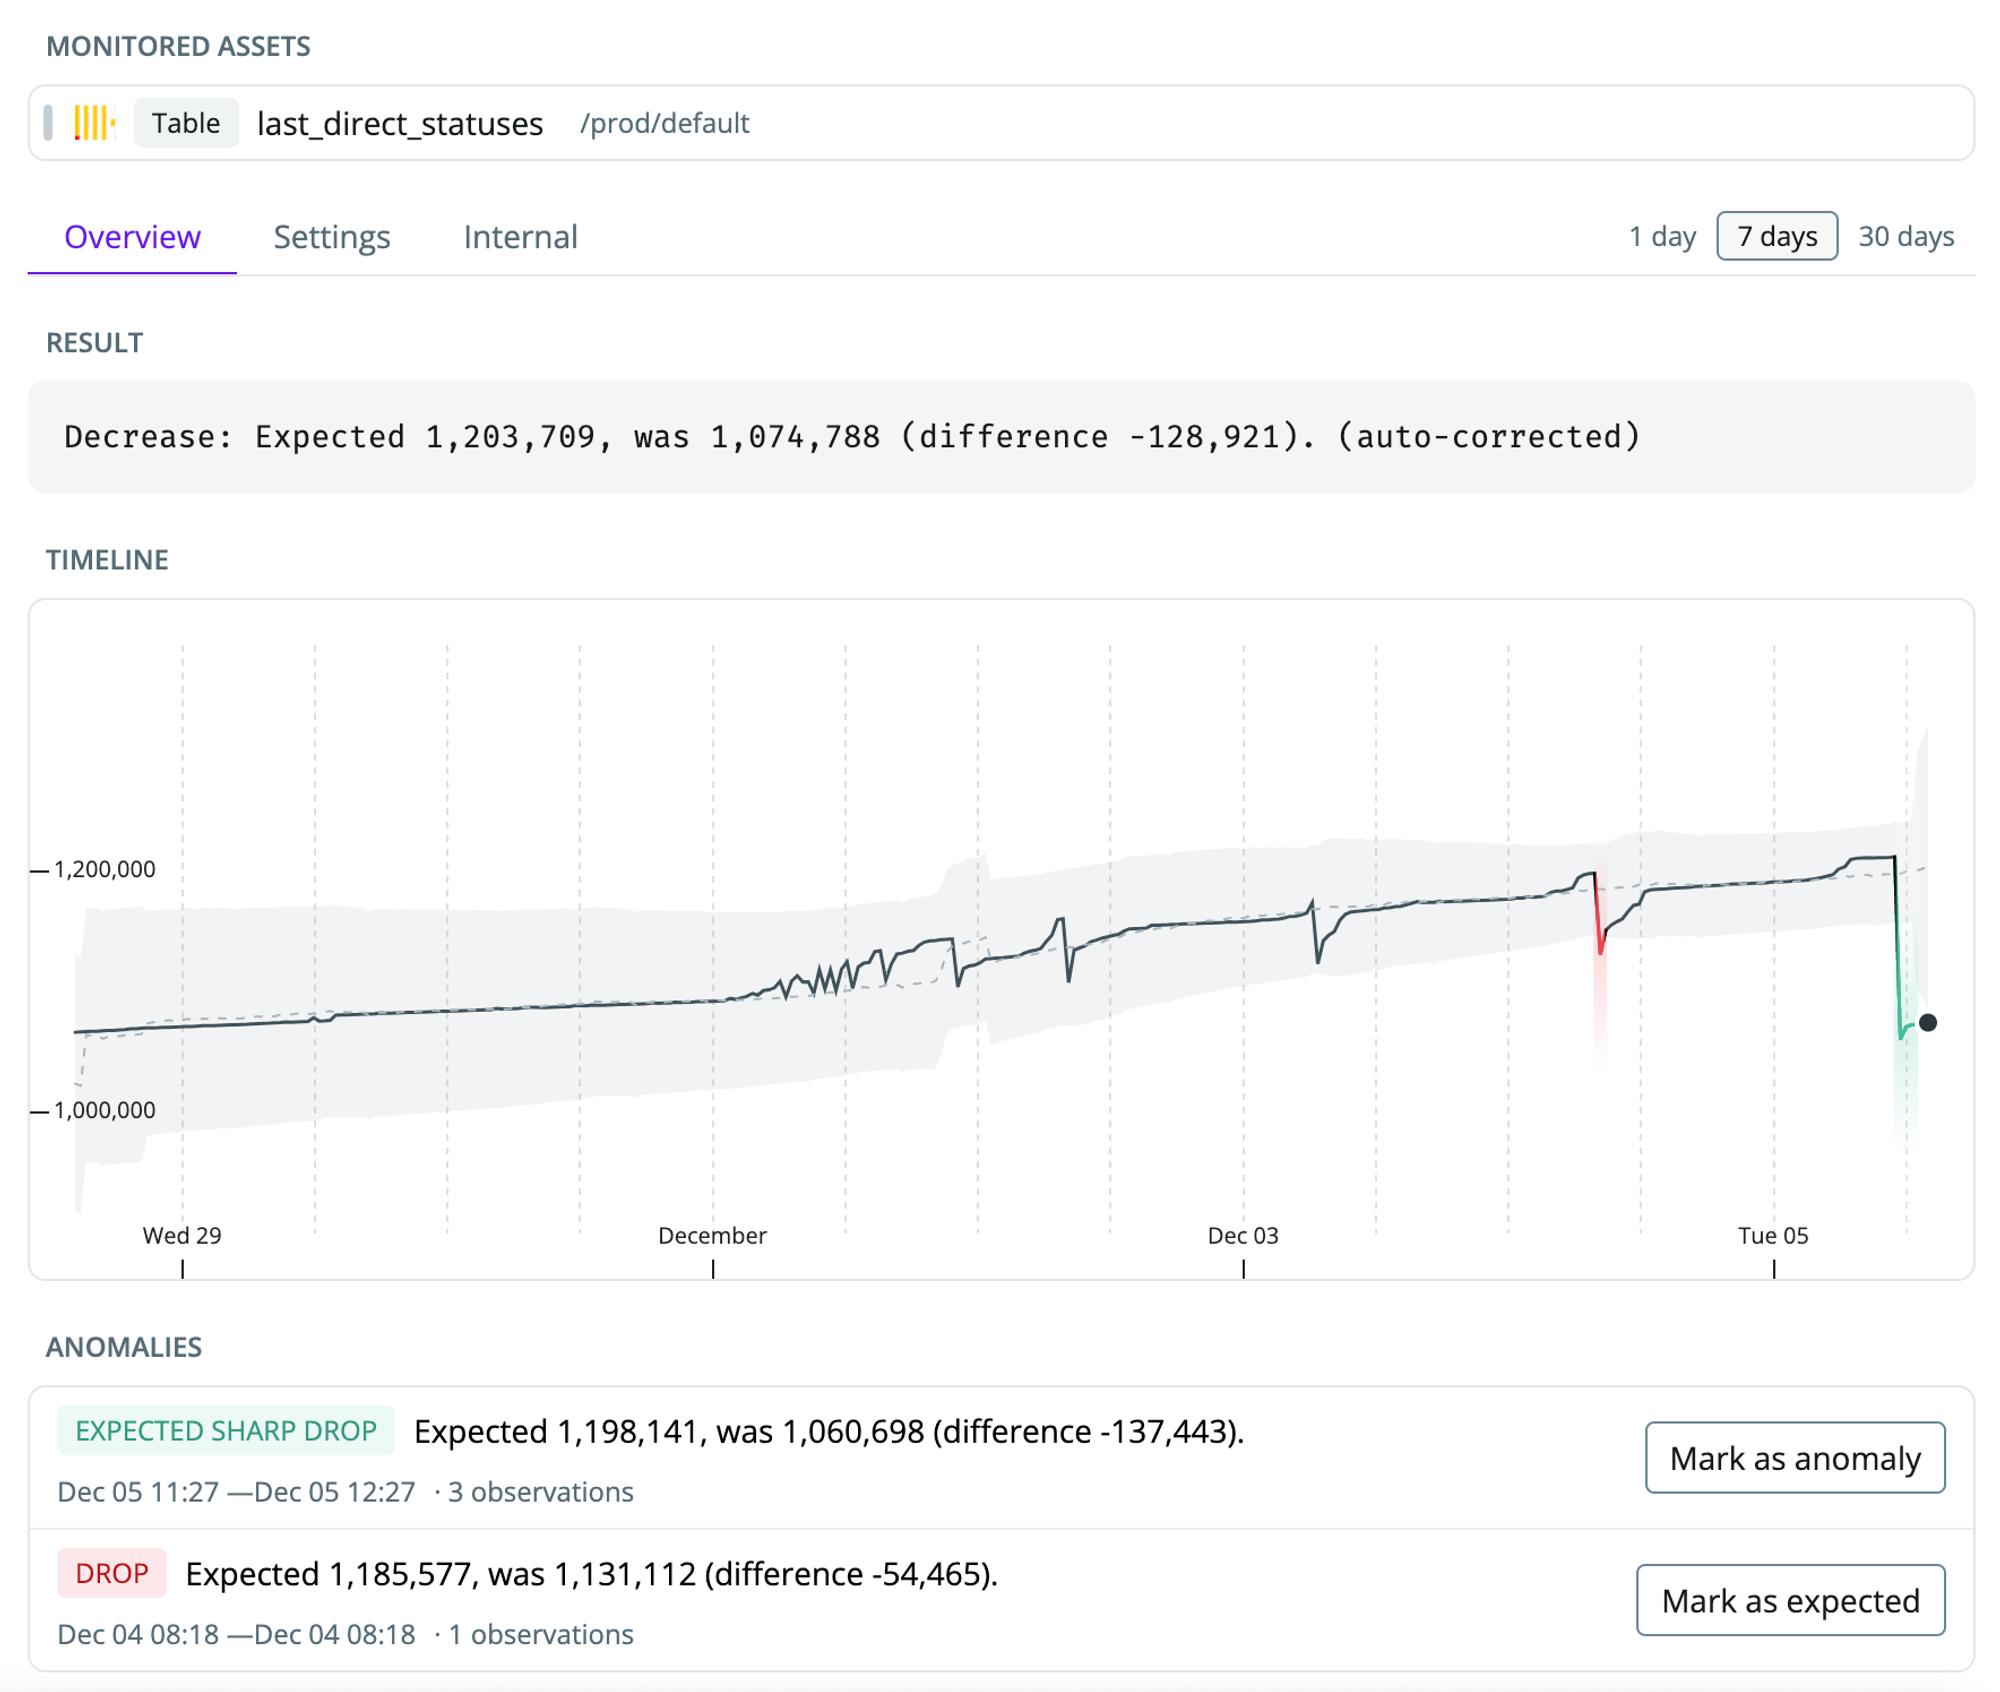
Default volume monitor
The default volume monitor is theRow count metric of the table stats monitor. It reads the row count from your data warehouse metadata, such as row_count in the Snowflake table information schema, so it costs almost nothing to run even on many tables.
Set it up with a deployment rule that enables the Row count metric. See Setting up a table stats monitor.
Use the default volume monitor unless you need what only the custom monitor gives you, such as counting rows by a time column of your choice or by segment.
Custom volume monitor
The custom volume monitor queries your table. This gives you more options, such as choosing the time column or splitting the count by segment. Each monitor is configured on its own table, and running it adds to your data warehouse costs.A custom volume monitor counts the rows in each time partition, so it measures how much data arrived in each period. This makes it good at catching small changes, and periods where no new data arrived at all.
Setting up a custom volume monitor
-
Navigate to the table or transformation model (dbt model, SQLMesh model, Coalesce node) where you want to set up the monitor and click
Add Monitor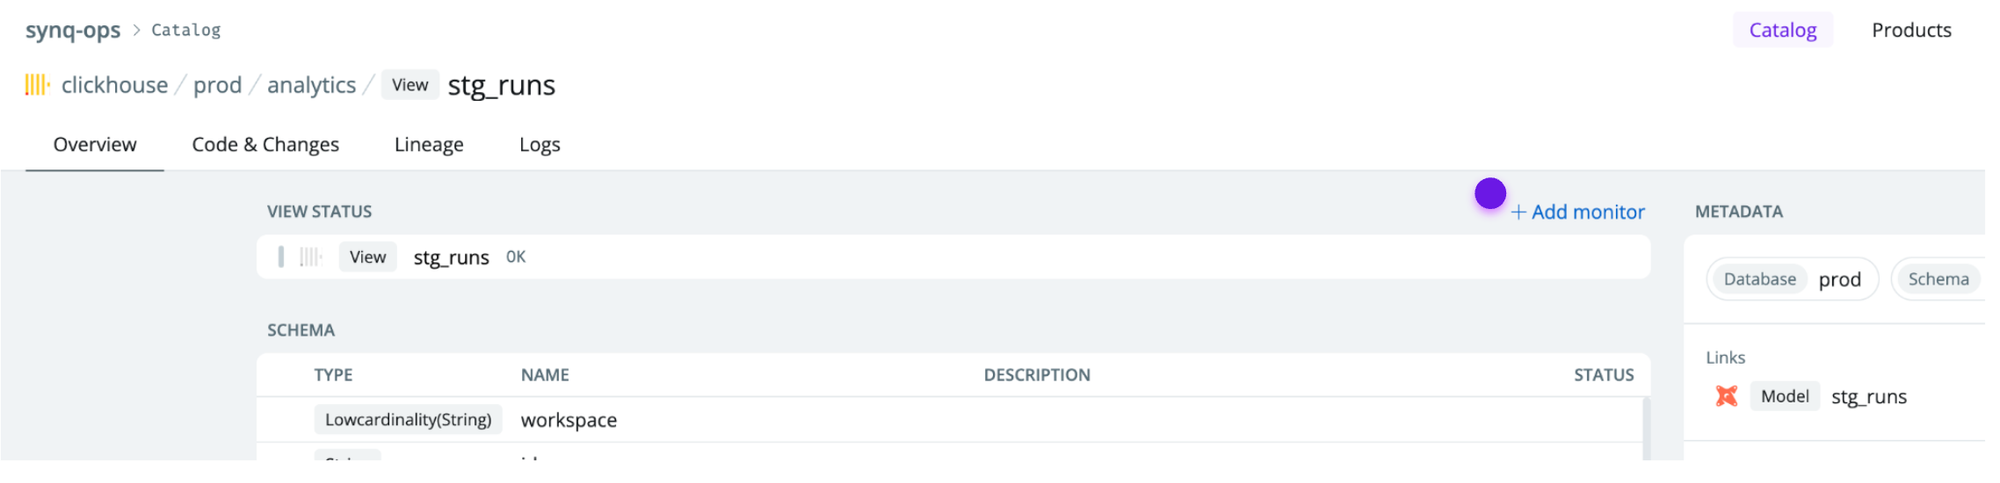
-
Select
Volumeto start creating a custom volume monitor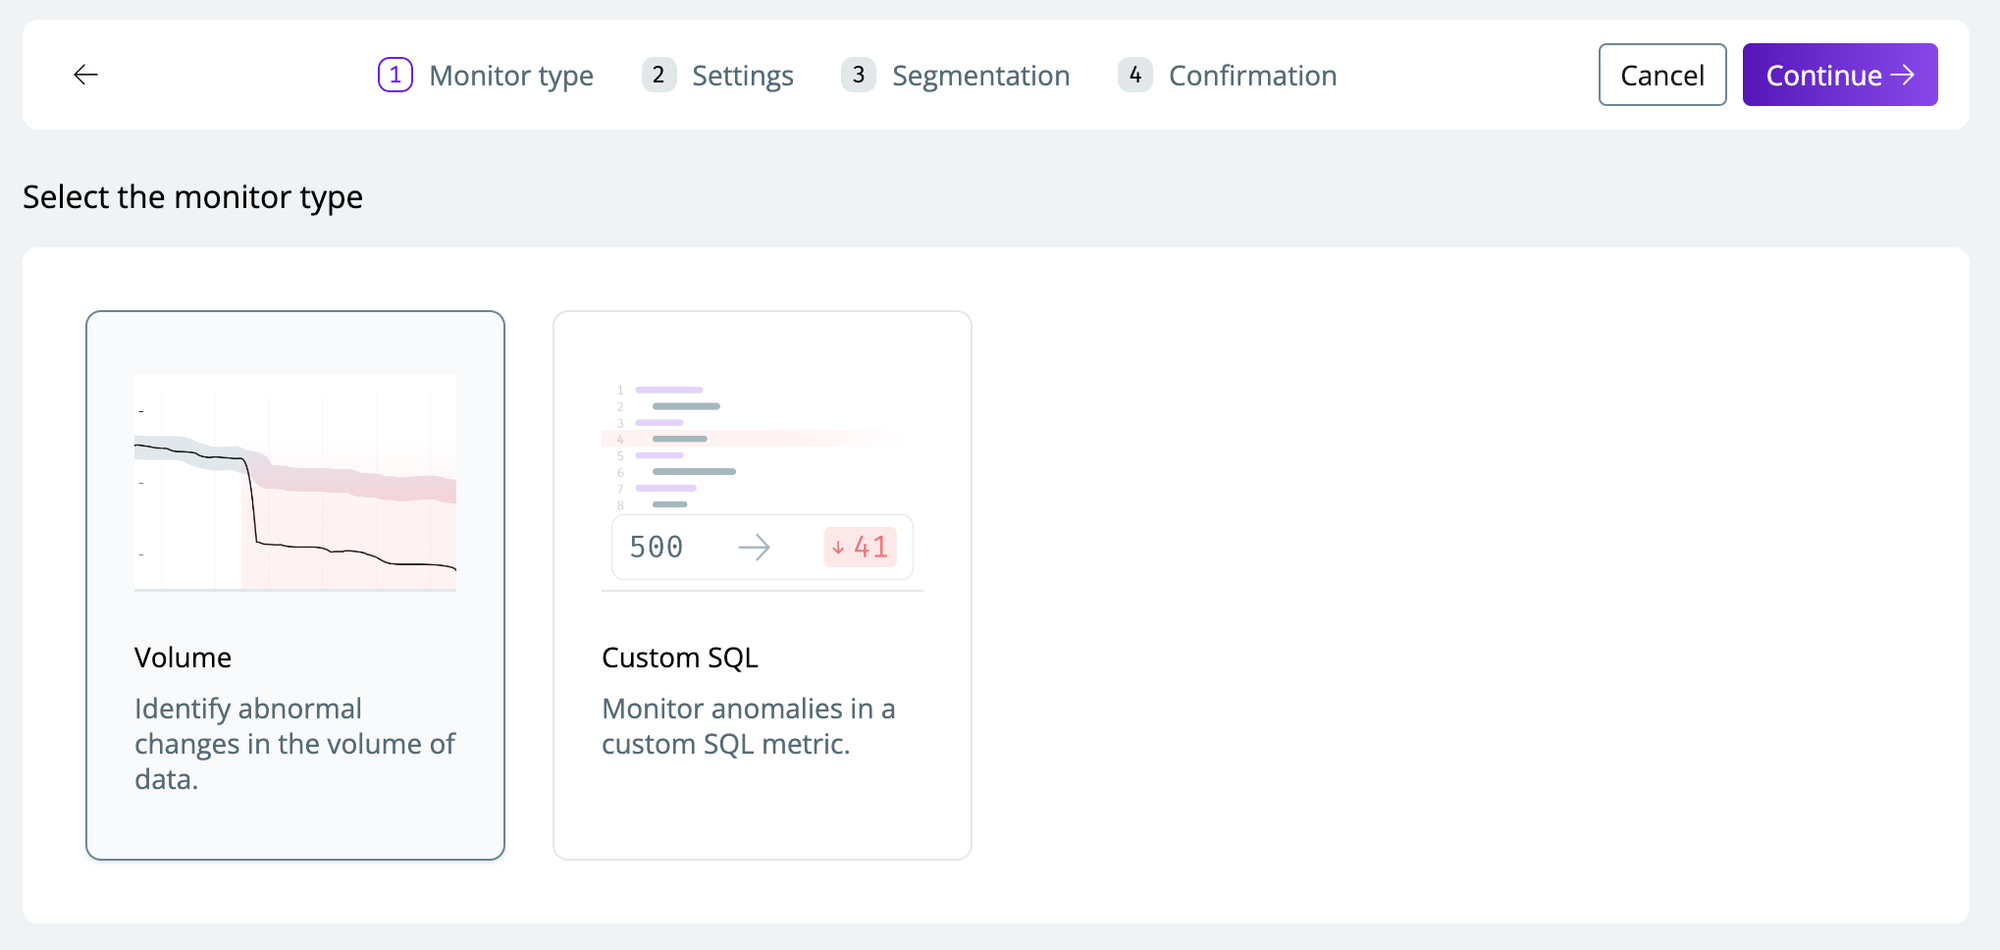
-
Configure the monitor with the relevant settings
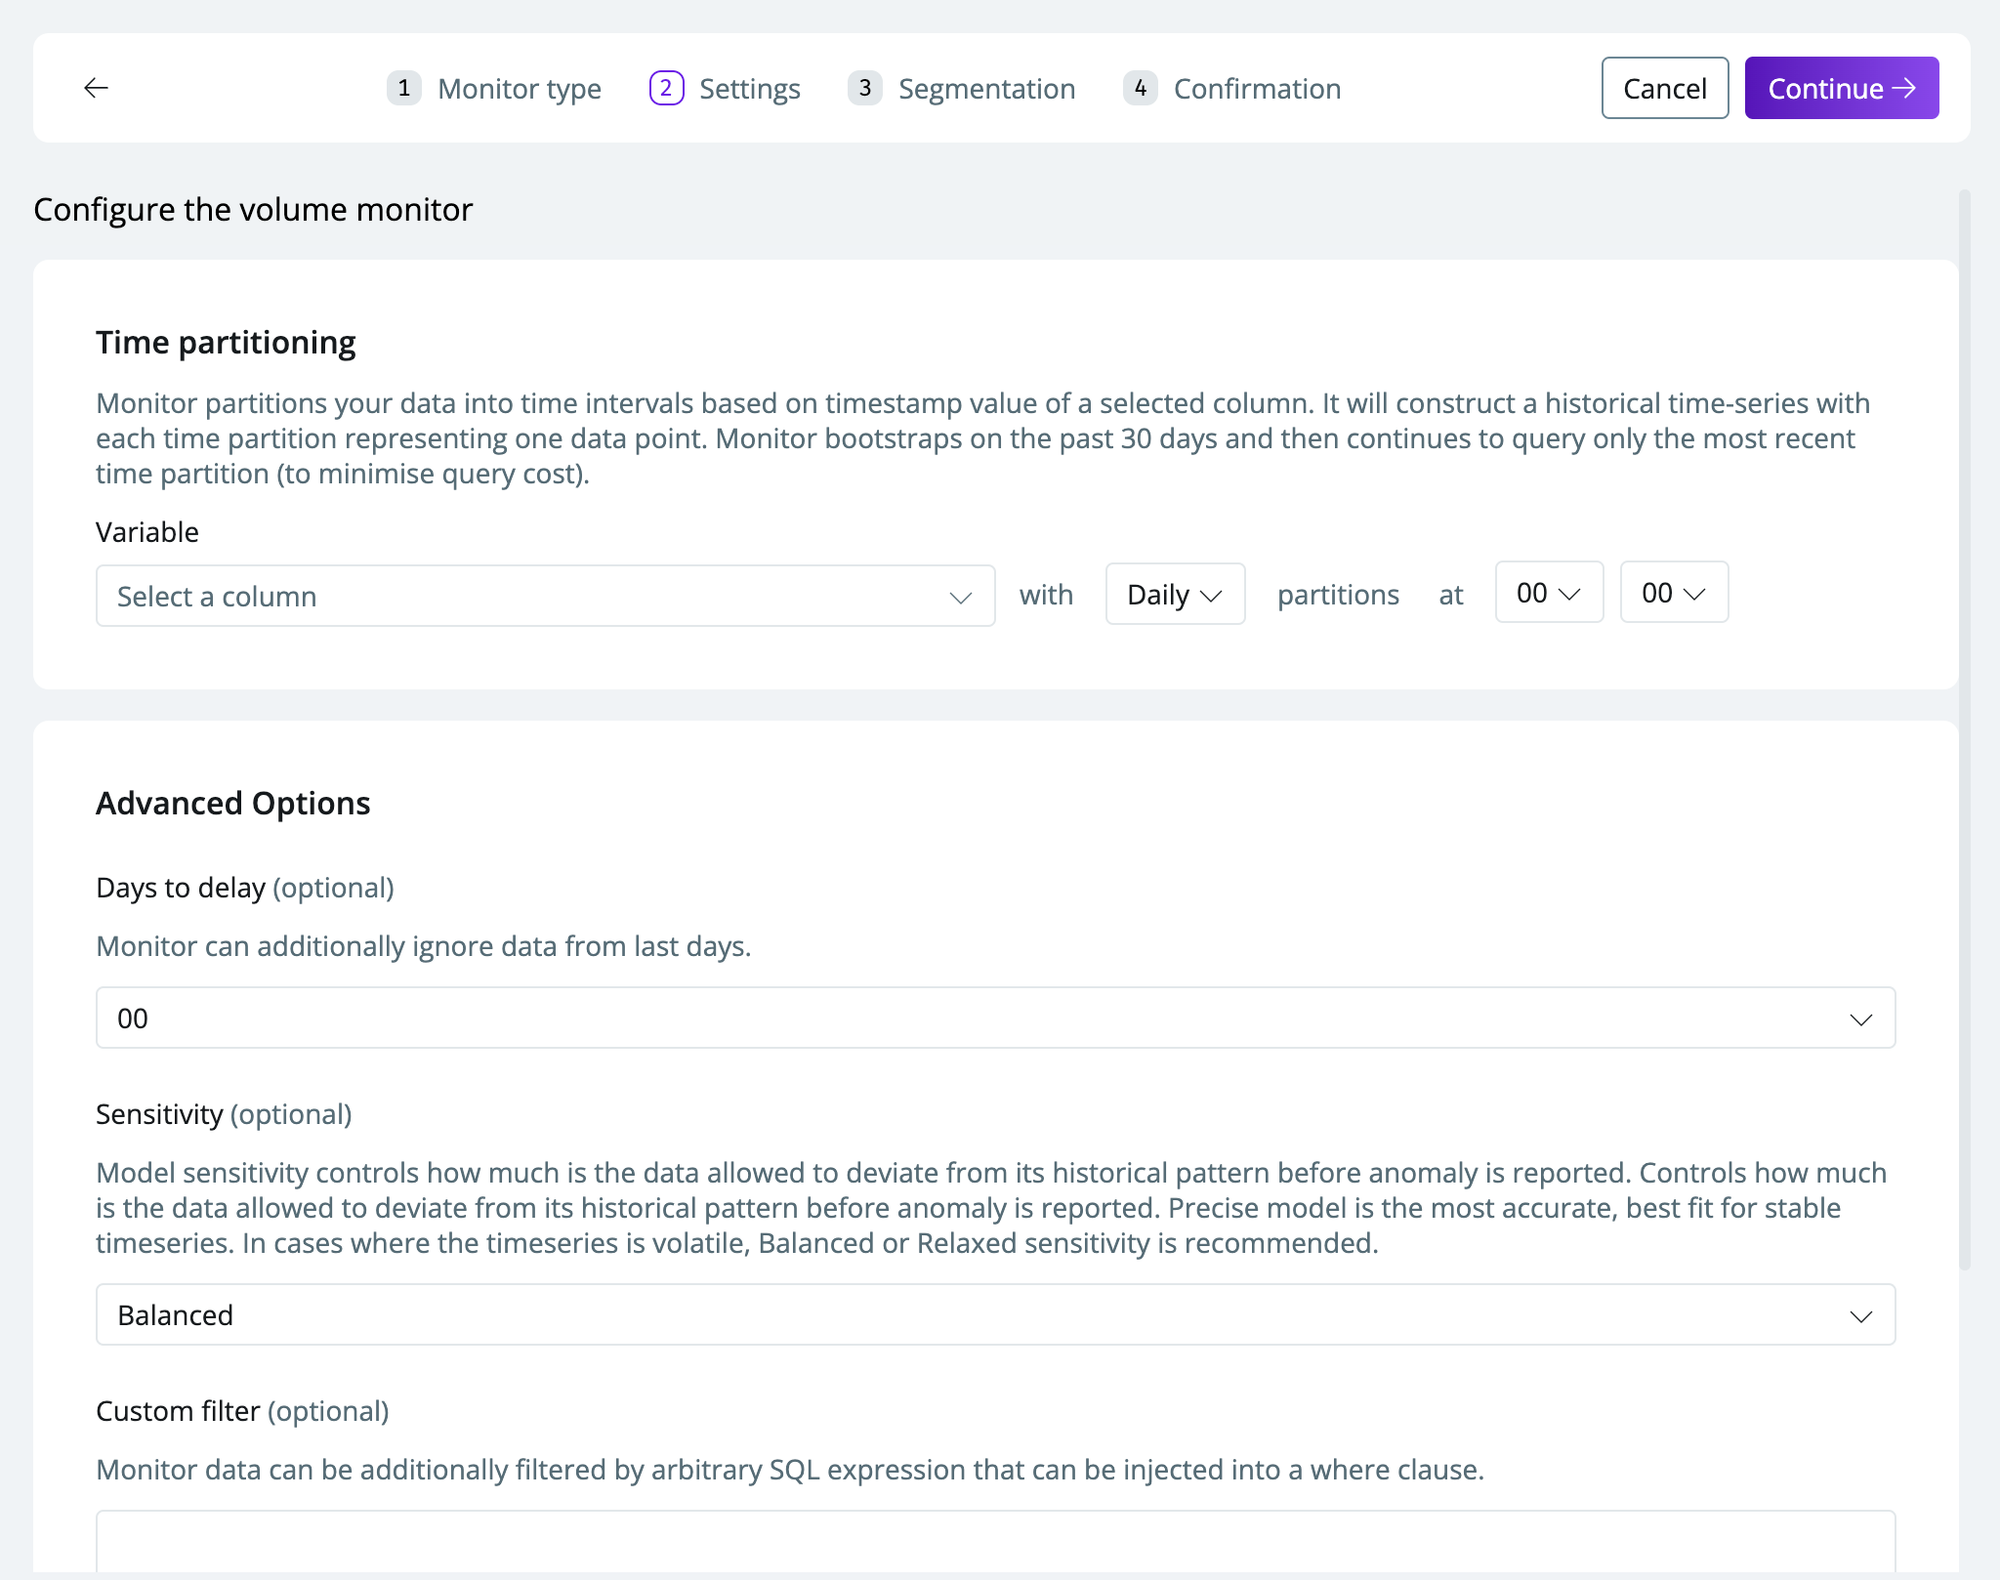
- Time partition: the timestamp column that splits the data into periods, for example
creation_date. - Delay: the number of recent periods to skip, if fresh data arrives late. See Time dimensions and scheduling.
- Detection mode: see Detection modes.
- Sensitivity: see Configuring monitor sensitivity.
- Custom filter: a SQL condition that limits the rows the monitor counts.
- Time partition: the timestamp column that splits the data into periods, for example
-
Select a
variableto segment by (optional). This will create multiple time series for each segment you select to include- If you only want to create a monitor for specific segments, toggle
Selected valuesand select the desired values - If you select
All values, new values are automatically added.
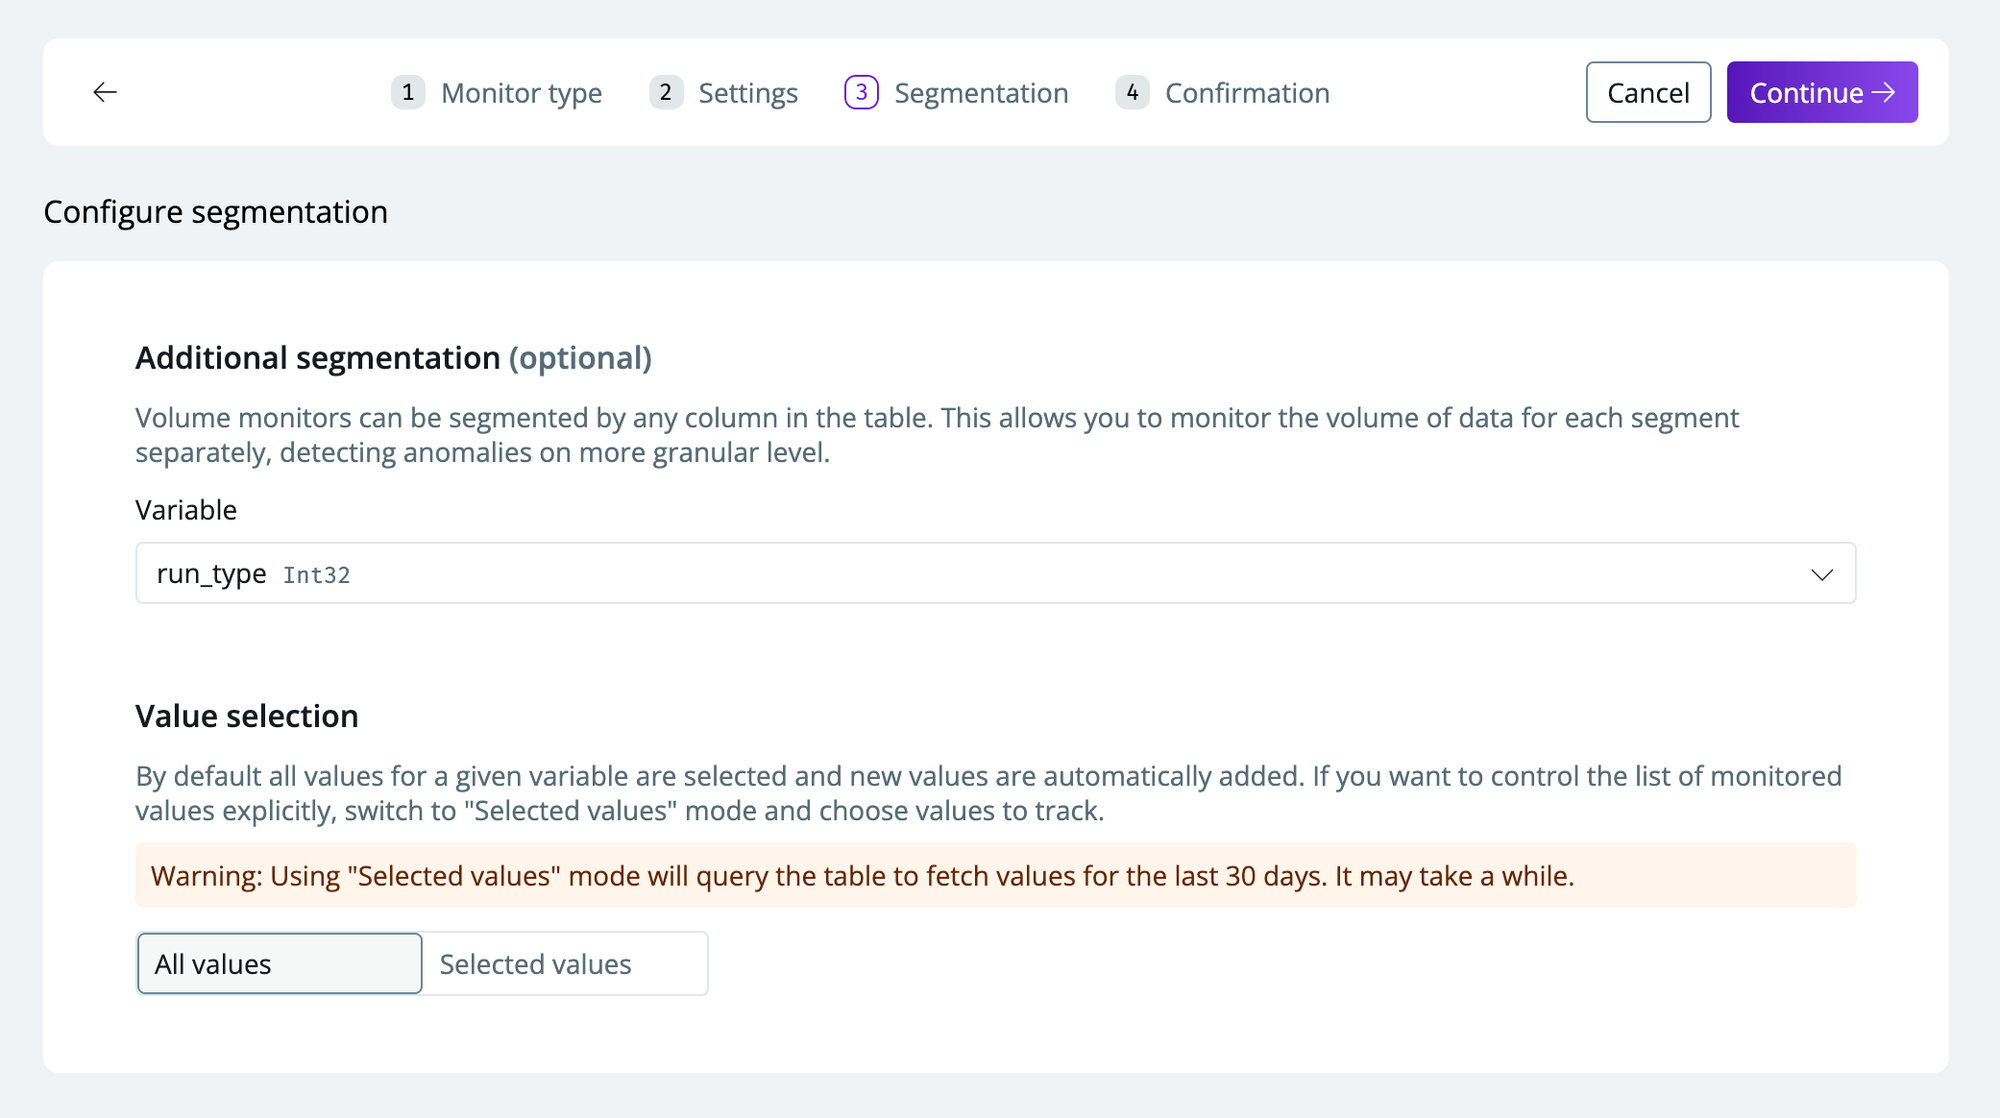
- If you only want to create a monitor for specific segments, toggle
-
Click
continueto set up the monitor with the specified configurations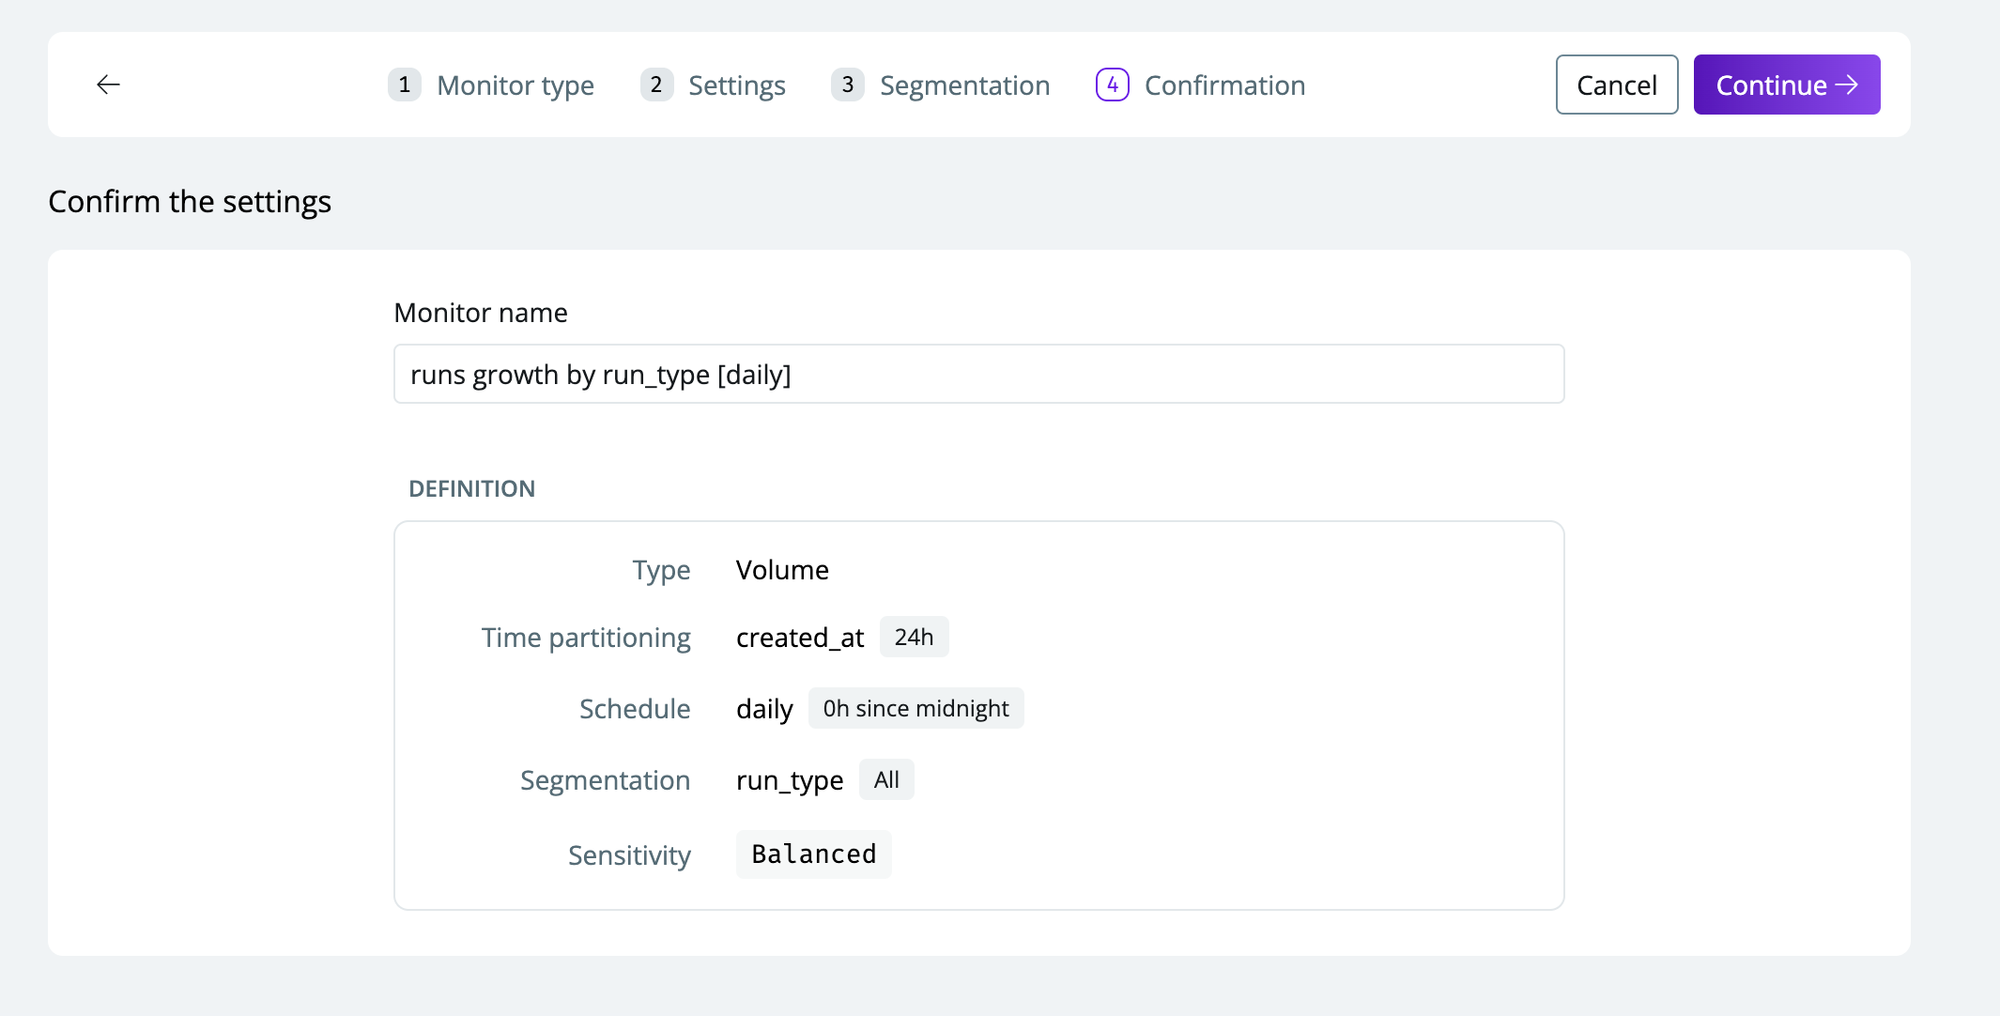
A custom monitor splits your data into time partitions by the selected timestamp column, and each partition is one point in the time series. On its first run, the monitor reads the recent history of the table. After that it queries only the newest partition, to keep query costs low. This means the monitor can detect anomalies right after you set it up.
Resetting a monitor
If you changed historical data and want the monitor to learn it again, open the monitor, clickSettings, and press Reset monitor. A reset cannot be undone, so only reset if you are sure.