

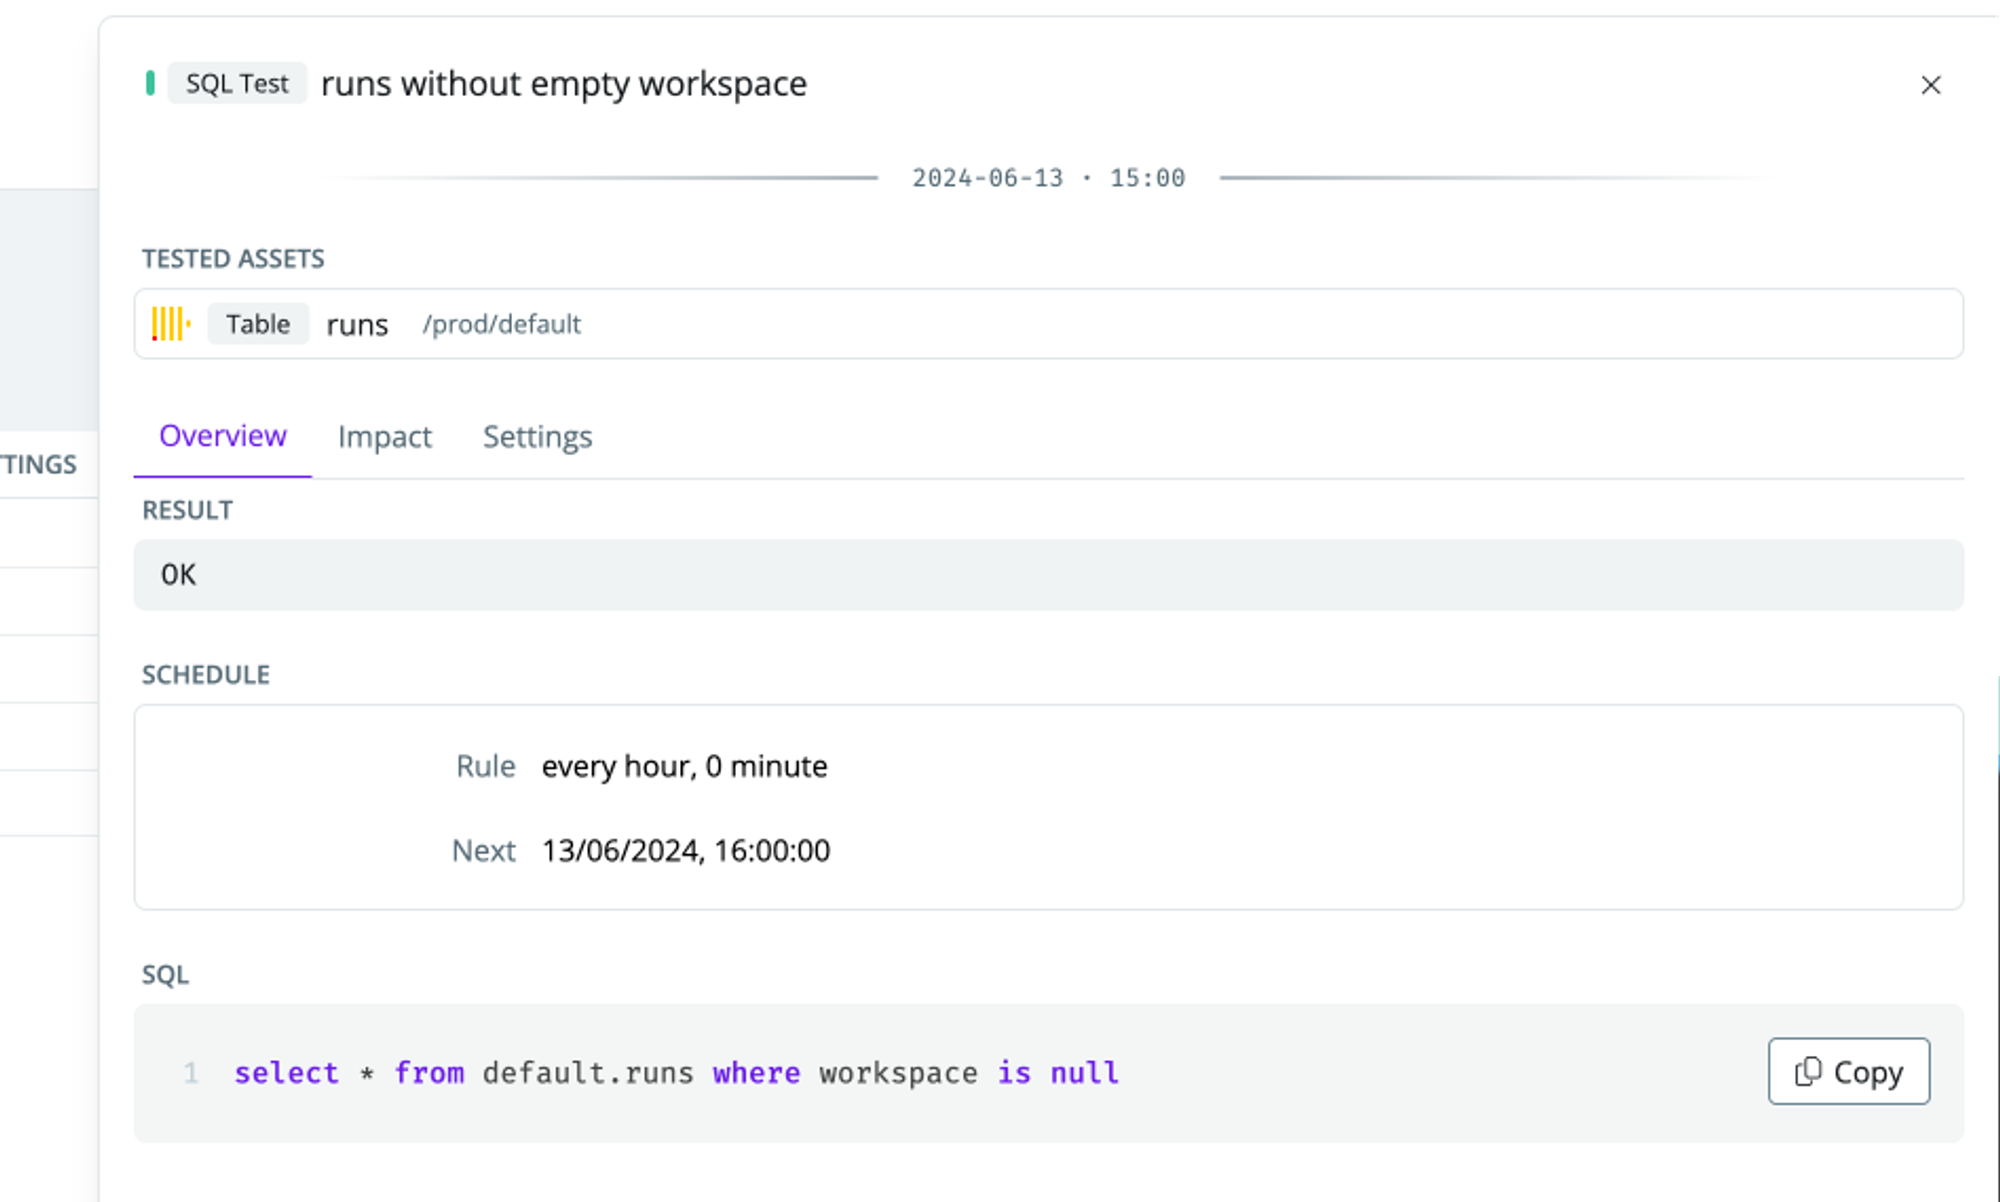
Example: a SQL test runs a query to check for rows where the workspace is null. If any rows match the test, it will throw an error
Test types
Alongside a query you write yourself, a test can be one of the following types. Each type takes the columns and values it needs, and works the same in the app, the API and YAML. In YAML, the name in the first column is thetype: value.
Creating a SQL test
- Head to the
- In the SQL tests section, click
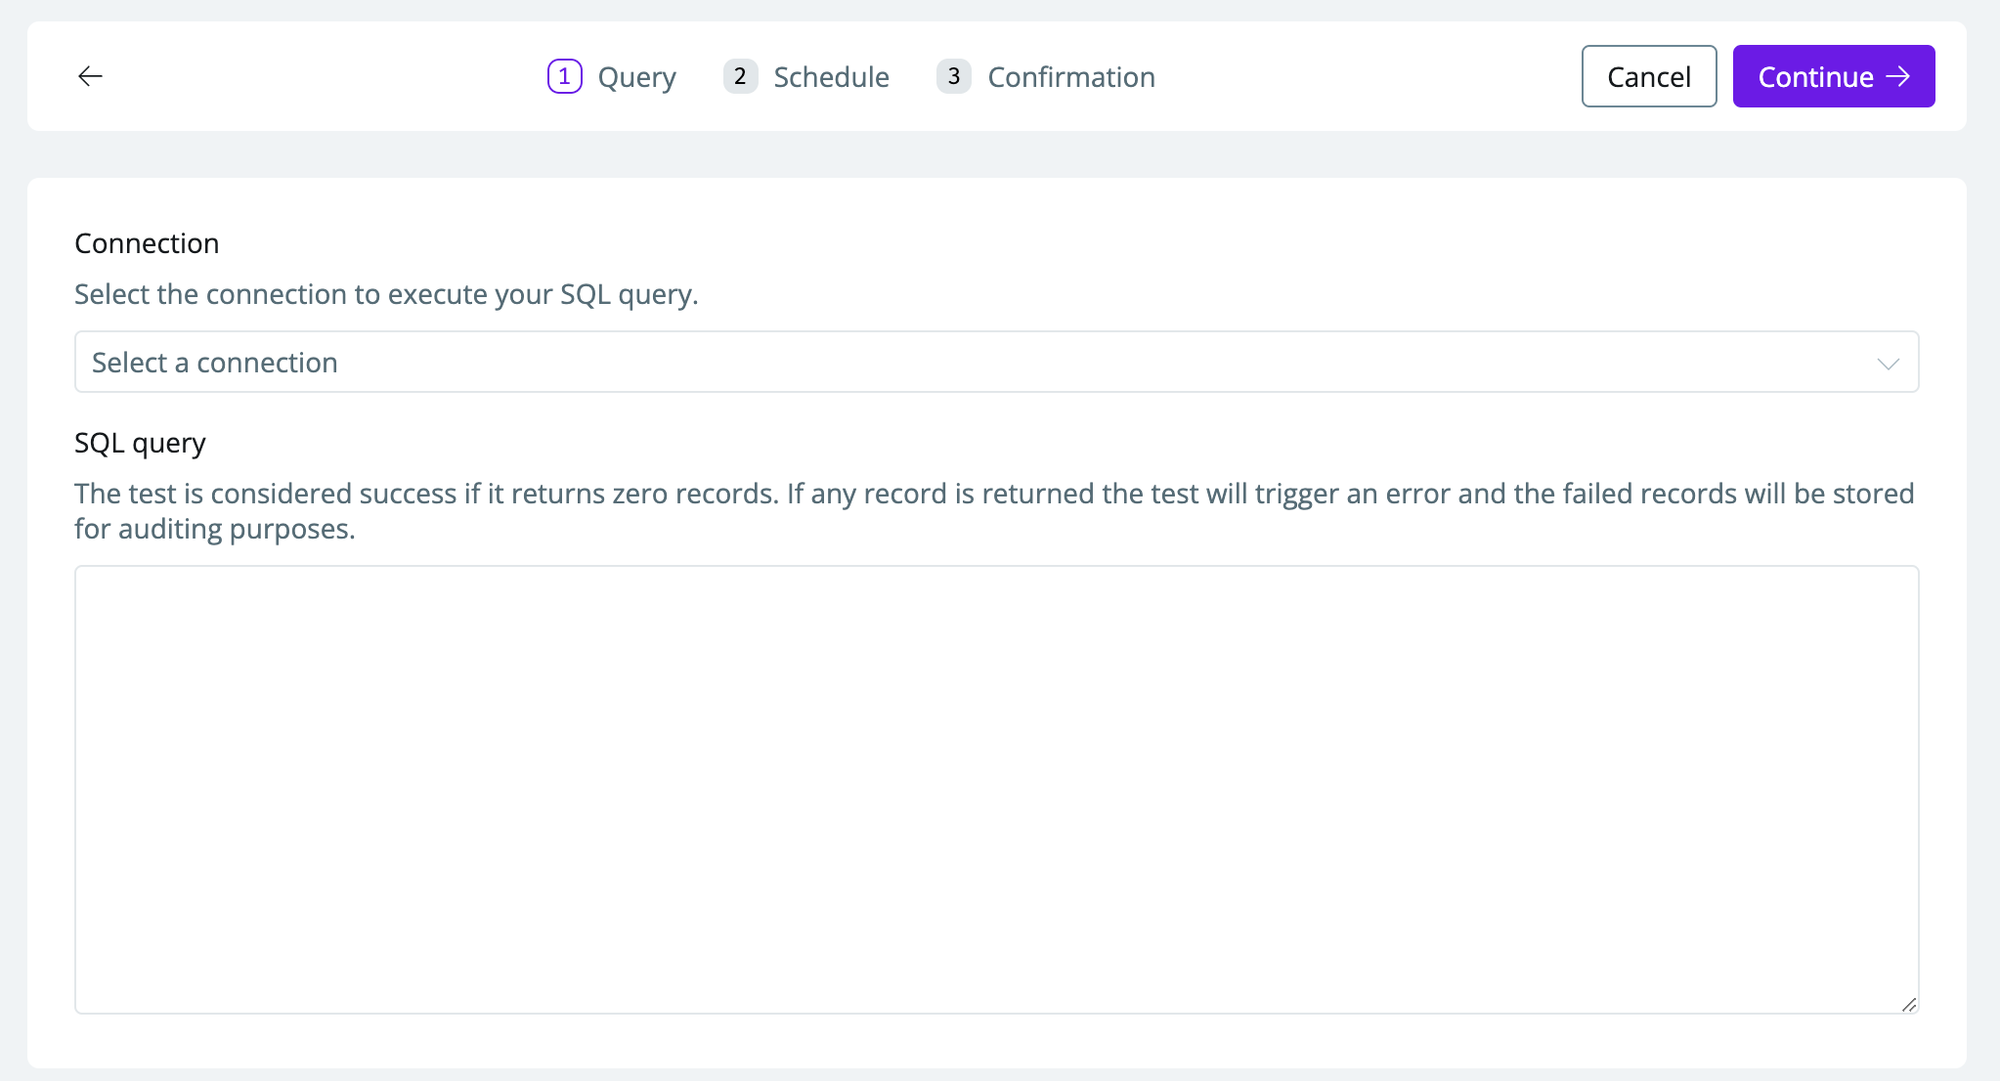
- Select the connection to execute your SQL query
-
Specify a SQL query. The test is considered a success if it returns zero records. If any records are returned, the test will trigger an error, and the failed records will be stored in an audit table for investigation. To have the query return metrics and grade them individually instead, add evaluators.
-
Choose a schedule (
hourly/daily) and a time (hh: mm) when you want the test to run.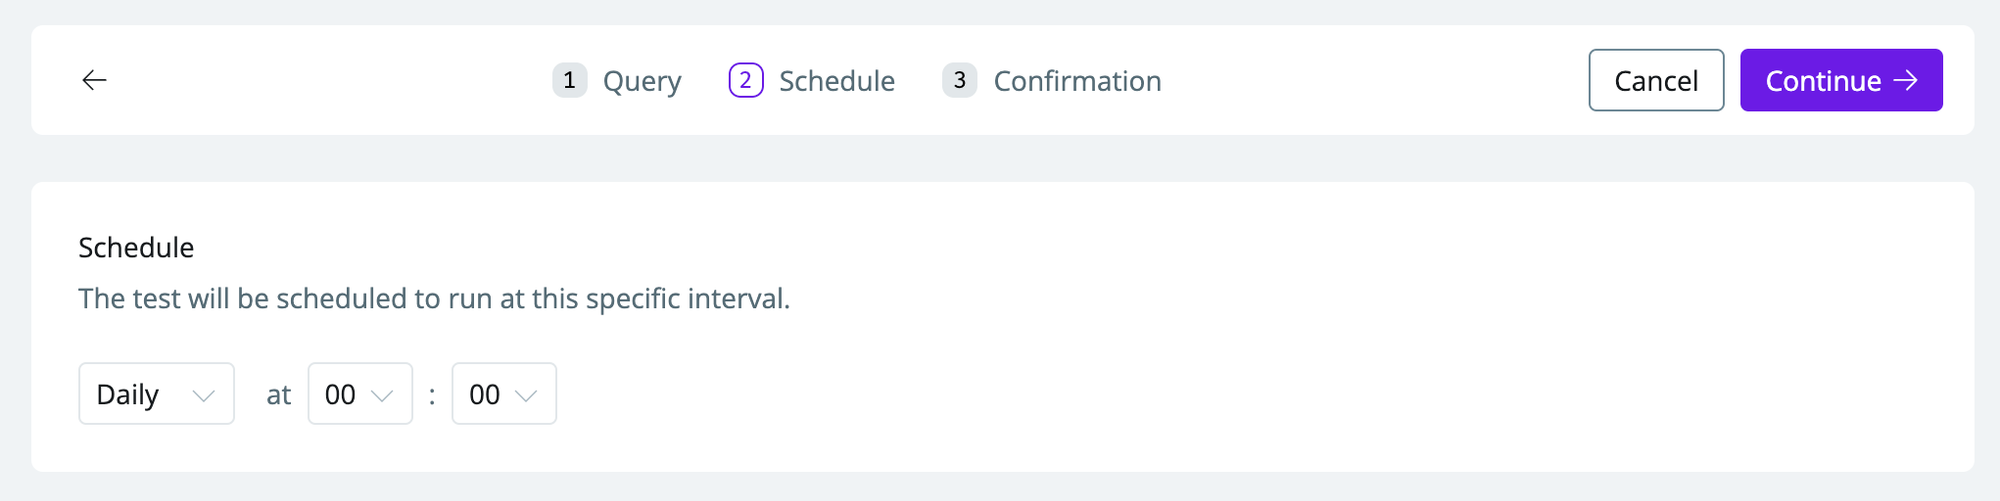
Running an excessive amount of tests or running a test too often will impact your data warehouse costs. Avoid running tests more often than needed
-
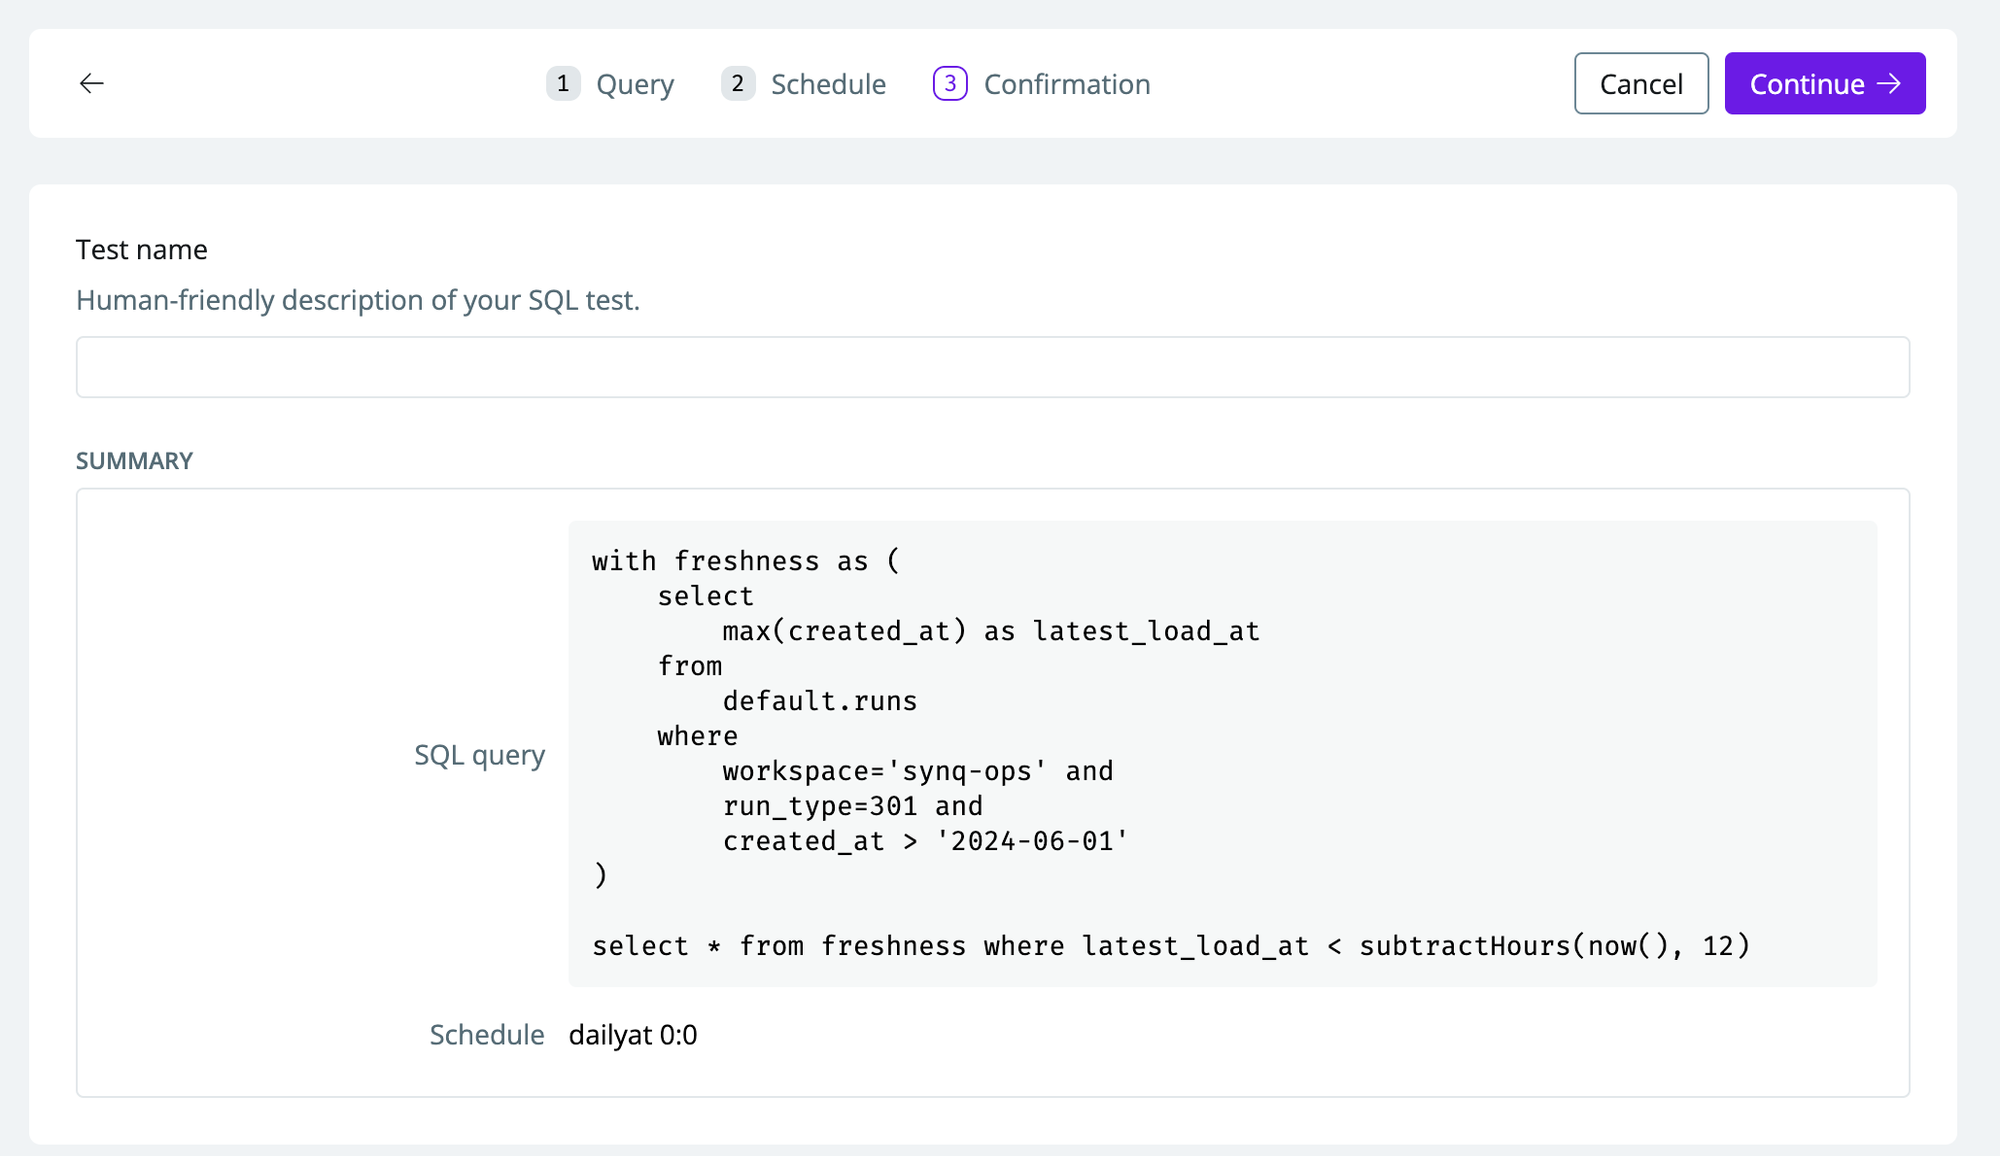
The confirmation page will show you a summary of the setup. To make it easier to locate in the UI, you can give the test a human-friendly name.
Editing a SQL test
- Head to the
- Click on to see all your SQL tests
- Select the SQL test you want to edit by clicking on it
-
In the popout, navigate to the
settingstab. ClickEditunder SQL test configurations to edit the name, run schedule, or SQL code. To delete the test, clickDelete SQL test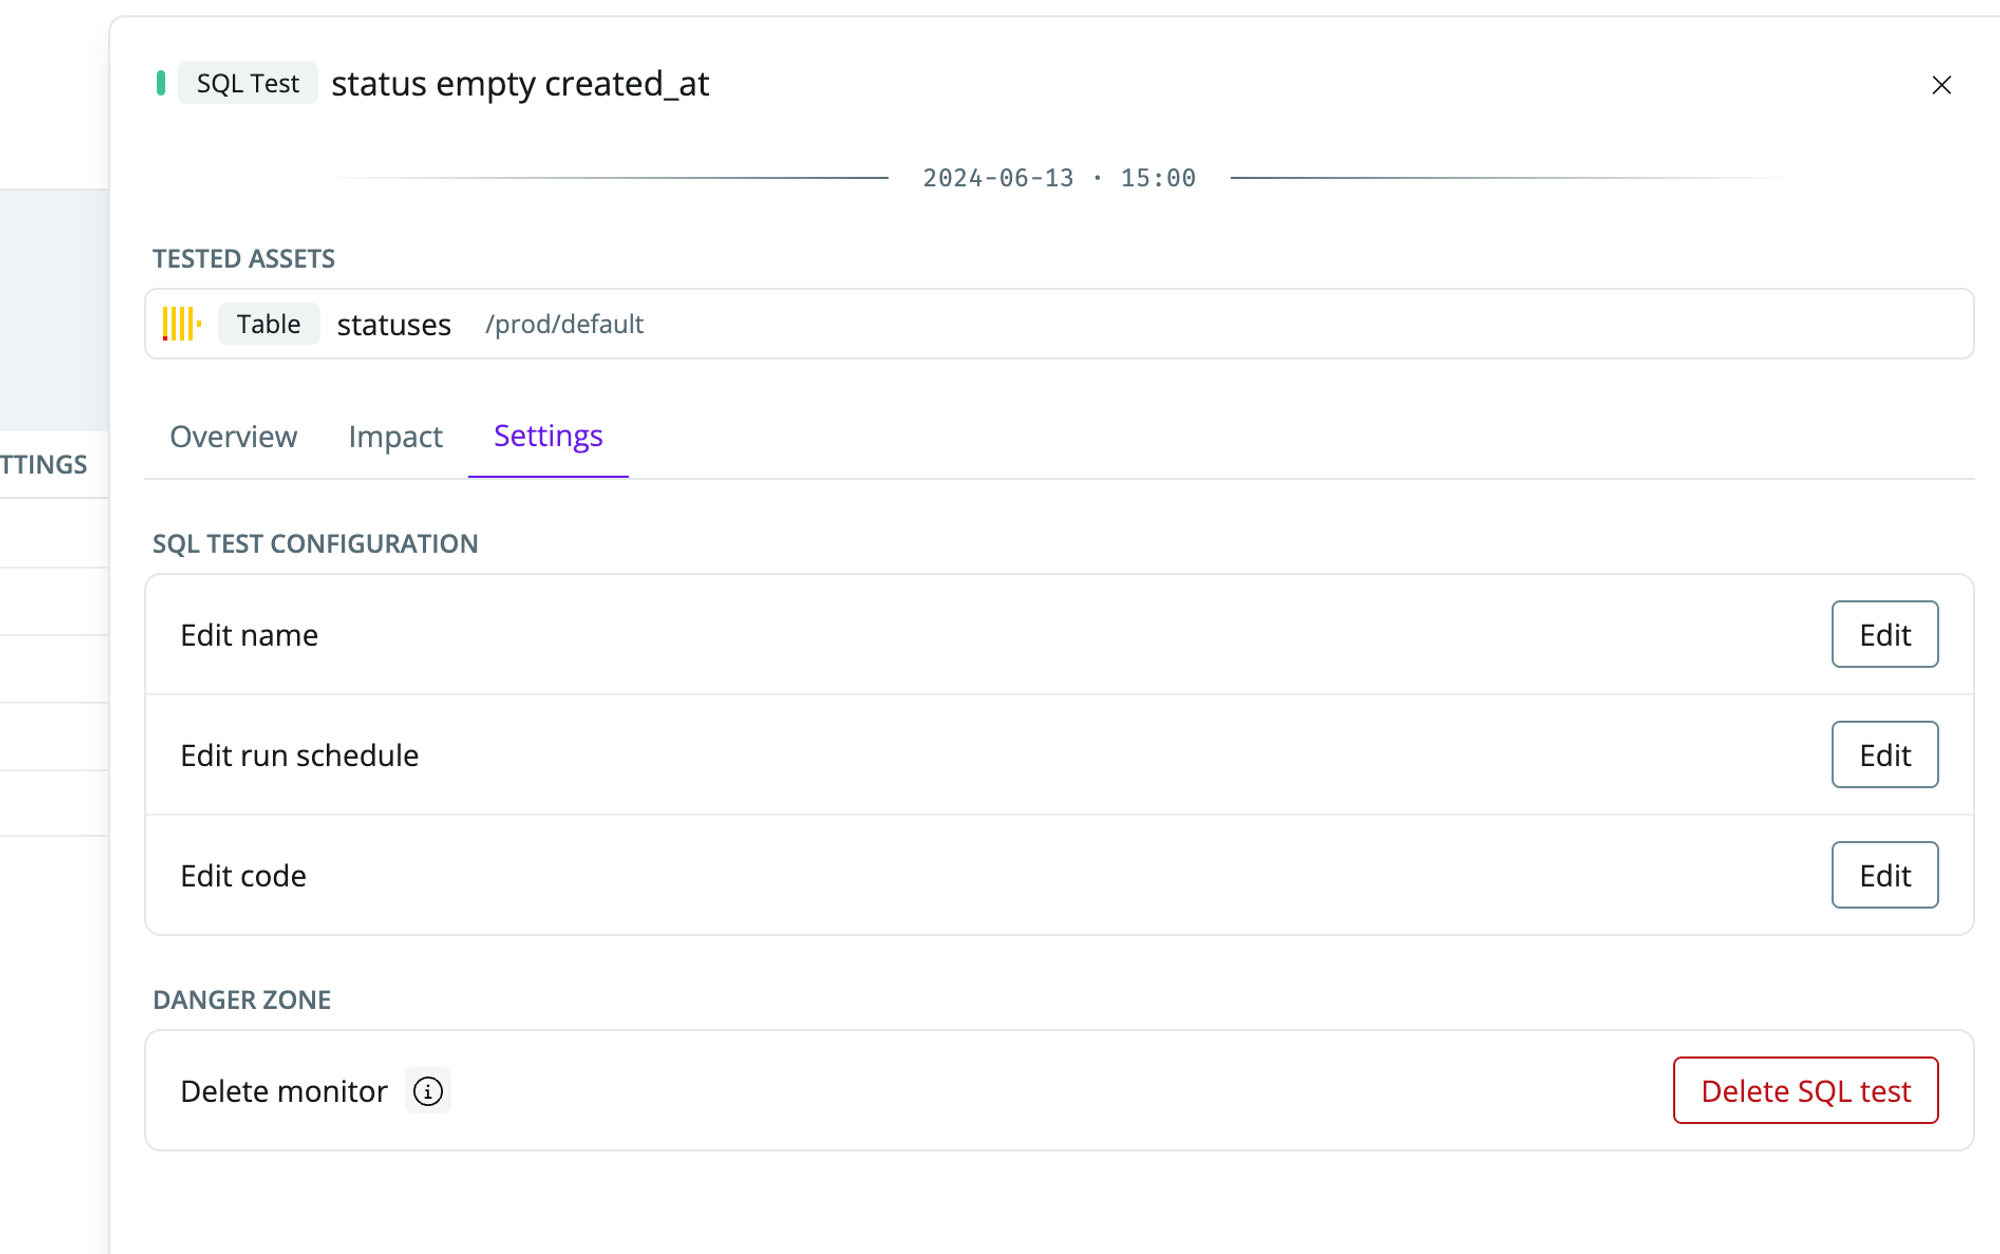
Managing SQL tests programmatically
SQL tests can be created and changed outside the app, one at a time or in bulk across every table matching a selection.- YAML and the CLI: tests live under an entity’s
tests:in a monitors-as-code configuration and are deployed withsynqcli deploy. To cover many tables by a selection instead of listing each one, put the tests under atype: sql_testsdeployment rule. - Public API:
synq.datachecks.sqltests.v1.SqlTestsServicefor individual tests andsynq.datachecks.sqltests.v1.SqlTestsDeploymentRulesServicefor rules that deploy a set of tests onto every table a selection matches. Reading needs a token withSCOPE_DATACHECKS_SQLTESTS_READ, writing needsSCOPE_DATACHECKS_SQLTESTS_EDIT. See the API reference and API scopes. - MCP: the SQL test tools create tests from a template (not-null, unique, accepted values, relationships, freshness, range, business rules) or from raw SQL, and the deployment rule tools do the same across a selection of tables. Listing tests is covered by read-only consent; writing needs the Deploy permission, and every write is confirmation-gated.
The table placeholder
Abusiness_rule and a business_query carry SQL you write yourself, so nothing in them names the table unless you do. Write {{ table }} and it is replaced with the fully qualified name of the table the test is anchored to, quoted for your warehouse. The other supported placeholders are the time placeholders. Any other {{ name }} token is rejected when the test is saved.
The substitution is textual, so the token is replaced everywhere it appears, inside a string constant or a comment as well as in a FROM clause. There is no escape sequence; write the name out yourself if you need the literal text in a result.
On a single test it saves repeating a name you already gave. On a sql_tests deployment rule it is the difference between a test and a copy: the rule deploys its tests onto every table the selection matches, so without the placeholder all of them run the same query against whichever table you typed.
business_query you own the whole statement and can alias it, which is what a correlated subquery needs. In a business_rule the FROM clause is generated for you and carries no alias, so the placeholder is for a subquery of your own rather than for qualifying a column:
{{ table }}.column is not portable: on BigQuery the fully qualified name is a single quoted identifier and cannot qualify a column. Reach for business_query when you need to name the anchor’s columns.
Time placeholders
A test that usesNOW(), CURRENT_DATE or a similar function checks different rows each time it runs. If you fix the data and run the test again, it does not check the rows that failed. Use the time placeholders instead. They work in the SQL of every SQL test: a query you write yourself, the sql_expression of a business_rule, the sql_query of a business_query, the SQL of an evaluator, and the tests of a sql_tests deployment rule. In the query editor of the app, type {{ to insert a placeholder.
When the test runs, each placeholder is replaced with a UTC timestamp literal in the SQL dialect of your warehouse.
Check only new rows
To check only the rows that are new since the previous run, filter on both ends of the window. Each window starts where the previous window ended. No row is checked twice and no row is skipped.{{ last_passed_at }} when all rows since the last good state must be checked again. While the test fails, its window grows on each run. After you fix the data, the next run checks the full period that failed. When it passes, the window becomes small again.
Filter on the time a row was loaded, if the table has such a column. A row can arrive late, with an event time in a window that was already checked. A filter on the event time does not check that row.
Compare a placeholder with a column
A placeholder has the type thatNOW() returns on your warehouse, so you can use it wherever NOW() works: loaded_at > {{ last_executed_at }}. Write it without quotes. '{{ executed_at }}' is rejected when the test is saved, because the value is already a timestamp.
Convert it only when the column is not a timestamp:
A comparison with a
DATE column is per day. Use >= at the start of the window, so the rows of the day of the previous run are checked again and none are missed.
Lookback
lookback sets how far back the placeholders can go, for example 6h or 1d:
- If a placeholder has no earlier run to take its value from, its value is
{{ executed_at }}minus the lookback. This is the case on the first run, and for{{ last_passed_at }}on a test that has not passed yet. - No placeholder is older than
{{ executed_at }}minus the lookback. When this limit applies, the run message says so, for example: “The lookback of 1 day limited the time window: rows before 2026-01-07T09:00:00Z were not checked.”
SqlTest.lookback, a duration.
If you do not set lookback, the first run looks back one interval of the schedule, or 1 day for a test without a schedule. The limit is seven intervals, and at least 7 days. A test from a sql_tests deployment rule always uses this default, and the rule does not accept lookback.
A warning for time functions
If the SQL of a test usesNOW(), CURRENT_TIMESTAMP, GETDATE(), SYSDATE, SYSTIMESTAMP, LOCALTIMESTAMP, CURRENT_DATE, CURRENT_TIME or LOCALTIME, the test is saved with a warning. The warning names the function and gives a suggested SQL. The suggested SQL replaces each function with {{ executed_at }}. For CURRENT_DATE it is CAST({{ executed_at }} AS DATE), and for CURRENT_TIME and LOCALTIME it is CAST({{ executed_at }} AS TIME). A call with a time zone, such as CURRENT_DATE('America/Los_Angeles'), stays as it is.
{{ executed_at }} is in UTC, while CURRENT_DATE uses the time zone of your warehouse session. If that time zone is not UTC, the suggested SQL can check a different day than your SQL. Check the suggestion before you use it.
You see the warning in these places:
- The query editor in the app shows the warning and the suggested SQL as a diff. Click Use suggested SQL to use it. If Scout is set up, you can also click Suggest a rewrite with AI. Scout suggests a rewrite to the placeholders and gives the reason. The rewrite is applied only when you click Use AI suggestion and save the test.
synqcli deployprints the warning, followed bySuggested SQL:.- The public API returns it in the upsert response, in
warnings[].suggested_sql_expression. - The MCP tools
create_sql_testsandupdate_sql_testsreturn it in their results.
{{ last_executed_at }} makes the test check different rows. Decide on that change yourself.
Run a test again
You can run an earlier execution of a SQL test again with its time values, for example after you fix the data, or to look at a failure. The run uses the current SQL of the test and the placeholder values of that execution, so it checks the same rows. Later scheduled runs do not take their values from it.- App: open the run of the SQL test and click Run again. You need a role that can edit SQL tests. The run shows the placeholder values under Time window.
- API: send
POST /api/datachecks/scheduler/v1/trigger/sql-test-run-againwith theexecution_idof the earlier execution. This isTriggerService.TriggerSqlTestRunAgain, and it needsSCOPE_DATACHECKS_TRIGGERorSCOPE_DATACHECKS_SQLTESTS_EDIT. It accepts theexecution_idof a trigger result, or theidof an execution from the executions API. The result has thetime_valuesof the run and thererun_of_execution_id. - MCP: use the
run_sql_test_againtool.
Evaluators
Abusiness_query with no evaluators is a single verdict: every row the query returns is a failure, so the query itself has to encode what “wrong” means and the whole test is one pass or one fail. Evaluators split that in two. The query returns the numbers, and each evaluator is a named condition over those numbers with its own severity. One scan of the warehouse, several checks, each of them named in the alert.
Reach for them when one rollup answers several independent questions, when those questions deserve different severities, or when you want the alert to say which condition broke rather than how many rows came back.
Daily order health by channel
The query groups yesterday’s orders by sales channel and computes four numbers per channel. Each evaluator reads one of them. SQL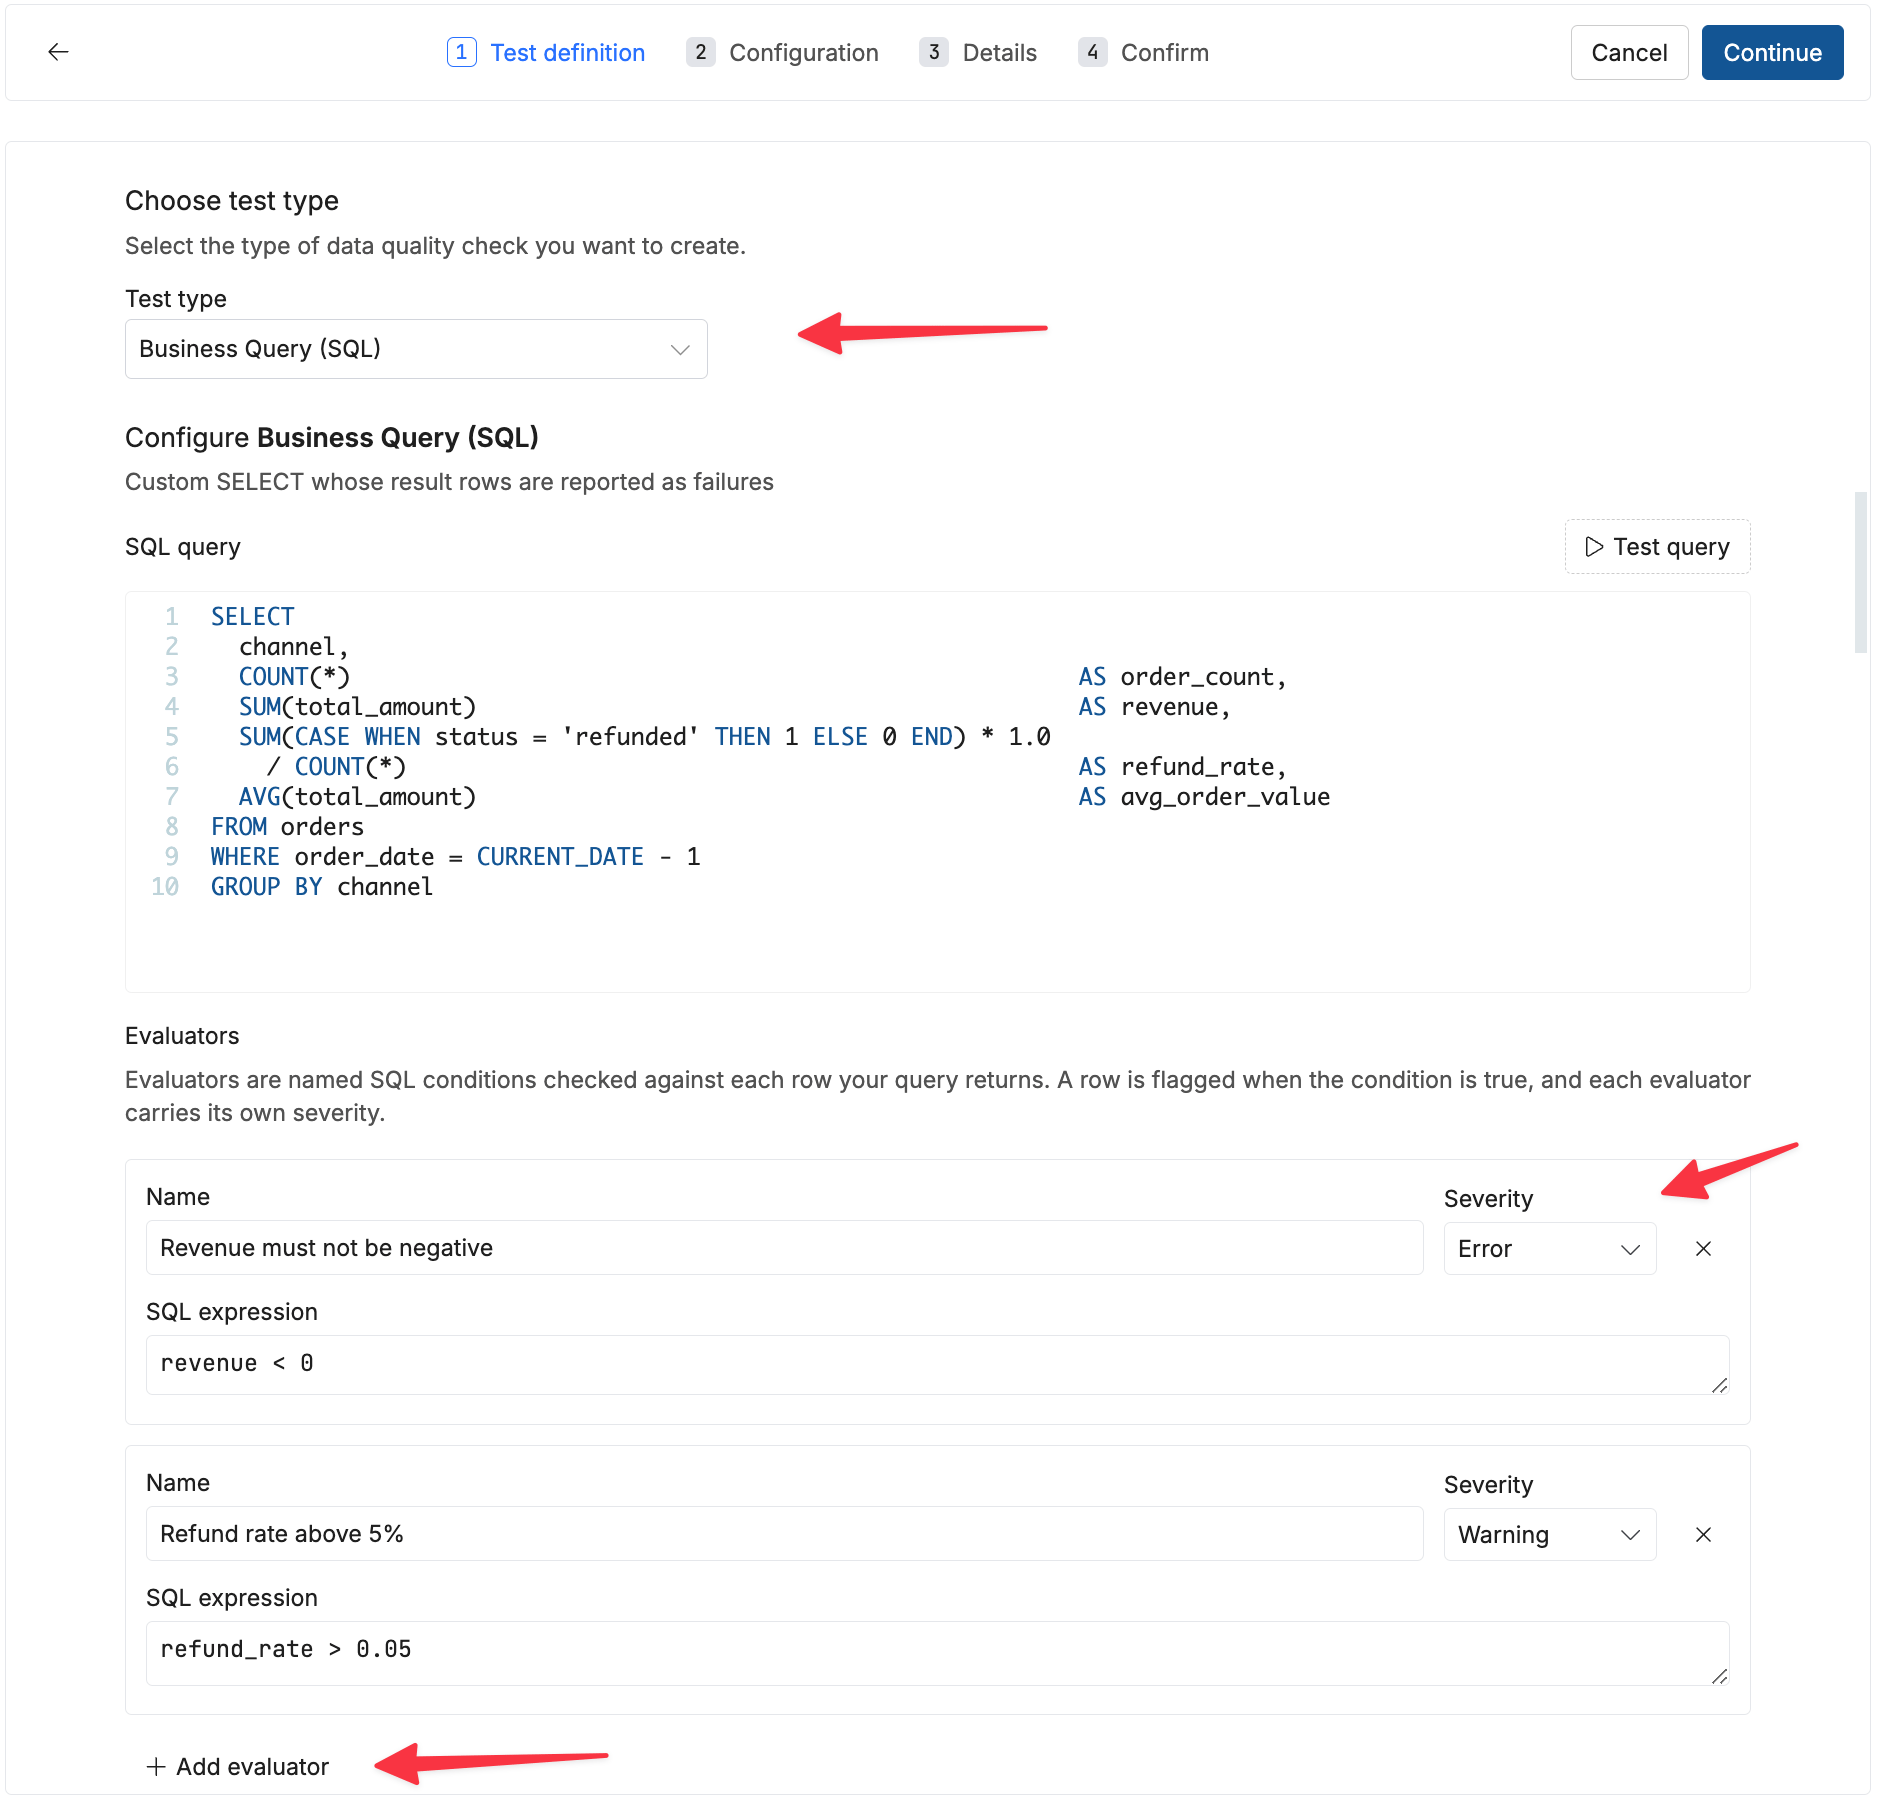
The same test in the app: the query, then one card per evaluator carrying its own name, severity and expression. The first two of the four are shown.
WHERE clause and its own scan of orders, or one test that returns a row when anything at all is wrong and cannot say what.
Writing an expression
- Refer to the columns of the query’s select list by the alias they were given.
refund_rateworks because the query aliased it. - The expression is a fail condition. The row is flagged when the expression is
TRUE, so write what you do not want to see rather than what you expect. NULLpasses. A metric that can be null and should count as a failure has to say so:revenue IS NULL OR revenue < 0.- Aggregate in the query and compare in the evaluator. The expression is evaluated one result row at a time, so it cannot total across rows.
- The expression is sent to your warehouse as written, in that warehouse’s SQL dialect.
Severity
Each evaluator carries its own severity, and the test reports the worst severity among the evaluators that flagged a row.
An
Info evaluator records its outcome without moving the test’s status, which suits a threshold you are still calibrating or a number you want in the run history without paging anyone. A test created over the API or from a YAML configuration can leave an evaluator’s severity unset, and it takes the test’s own.
Failed rows
With Save failures on, the rows an evaluator flagged are written to the audit table, alongside how each evaluator did on that run. You can go from a failing test to the channels behind it rather than to a count. Rows are written whenever any evaluator flags one, including when onlyInfo evaluators did and the test itself reports OK. A threshold you are still calibrating therefore collects real rows before you promote it to a warning.
Editing evaluators
Adding, removing or changing an evaluator updates the test in place, so its history, its issues and its past runs are kept. A test on a schedule runs again straight away instead of waiting for its next slot, so the change shows up in the run view immediately.Evaluators belong to a
business_query, because the evaluator reads the columns the query returns and only a business_query gives you the whole SELECT.Audit table schema
When a test has Save failures on, the rows it flagged are written to an audit table in your data warehouse, so you can look at the records themselves. The table belongs to the warehouse integration rather than to any one test: set its fully qualified name in the integration’s Audit table FQN field and Coalesce Quality creates it if it does not already exist. While that field is empty a test writes nothing, whatever its Save failures setting.Naming the table
The name is yours to choose. Give the integration a fully qualified name the connection can create and write to; the placeholder in that field shows the shape your platform expects, from a bare table name on Redshift and PostgreSQL tocatalog.schema.table on Databricks and [warehouse].[schema].[table] on Microsoft Fabric. One audit table serves every SQL test on that integration, and the statements below use quality_sql_test__audit as the name.
Schema by data warehouse
The audit table schema varies slightly by data warehouse. Below are the CREATE TABLE statements for each supported platform:BigQuery
BigQuery
Snowflake
Snowflake
Databricks
Databricks
PostgreSQL
PostgreSQL
MySQL
MySQL
Redshift
Redshift
ClickHouse
ClickHouse
Trino
Trino
SQL Server
SQL Server
Microsoft Fabric
Microsoft Fabric
Oracle
Oracle
DuckDB
DuckDB
Column descriptions
The table is created when you save the integration with an Audit table FQN set, so the connection needs permission to create tables in that schema or database. Without the privilege the integration reports the failure on its status; you can also create the table yourself with the statement above and grant
INSERT on it instead. On Microsoft Fabric, the service principal needs the Contributor workspace role, see Microsoft Fabric.sql_test_name and evaluators columns keeps its original shape and those two
values are dropped from the rows written to it. Add the two columns yourself to start
recording them.